In the lifecycle of an Artificial Intelligence system, the transition from development to deployment is fraught with complexities that extend far beyond mere code. At the heart of every AI system lies a fundamental equation: Data + Algorithms + Training = Model. While much of the public discourse focuses on the "intelligence" of the model, the quality of that intelligence is inextricably linked to the quality of the data used to train it. When data is flawed, the resulting model inherits those flaws, leading to unpredictable and potentially harmful outcomes.
The Challenge of Noisy Data
Before a model can learn patterns or associations, the data must be processed and refined. However, real-world data is rarely perfect. "Noisy" data refers to errors and inaccuracies that can degrade a model's performance. These errors typically manifest in several ways:
Inaccuracies: Incorrect values, misspelled words, or bad labels.
Irrelevant Features: Data points that do not contribute to the specific task at hand.
Inconsistent Formatting: For example, a dataset where dates are recorded as both "September 16, 2026" and "09/16/26".
Missing Data: Incomplete values within a dataset that create gaps in the model's understanding.
These errors often stem from human error during manual entry, flaws in the data collection process, or external environmental factors.
Exam Tip: If asked to identify the source of model degradation, remember that noise isn't just "wrong numbers"; it includes inconsistency in format and the presence of irrelevant information that confuses the algorithm.
To combat these issues, data scientists employ three primary handling techniques:
Data Cleaning: The process of identifying and removing, or correcting, errors, inconsistencies, and irrelevant information.
Data Standardization: Ensuring all data follows a consistent format (e.g., making all dates follow the same convention).
Feature Selection: The strategic process of selecting only the most relevant features for a particular model to ensure efficiency and accuracy.
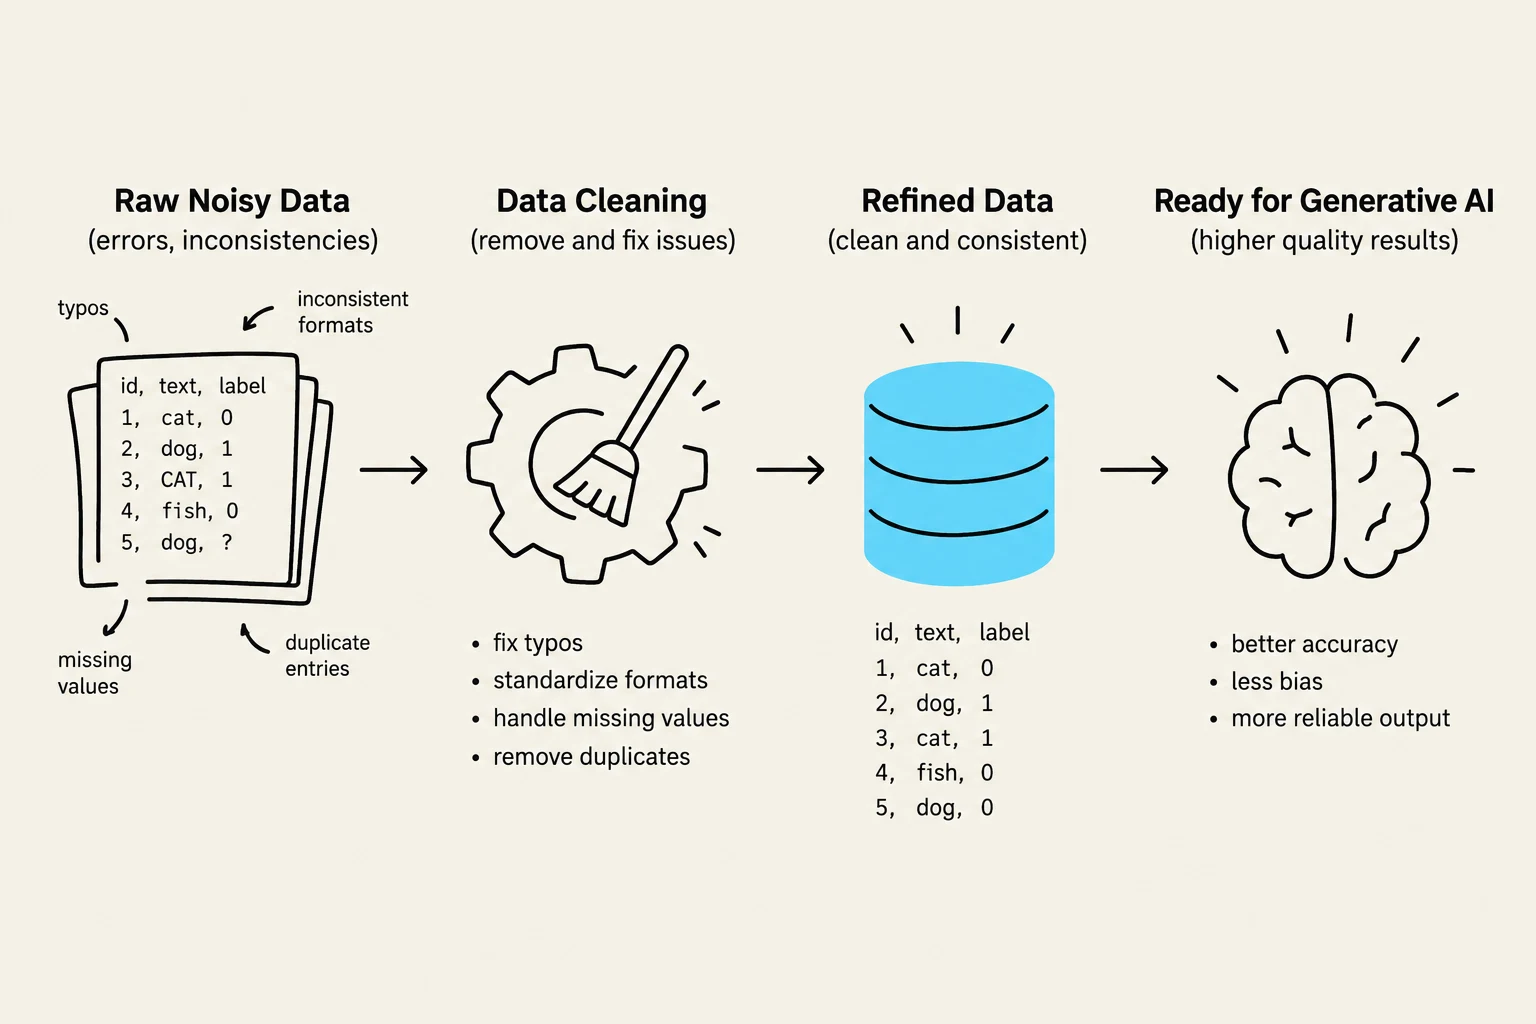
This diagram illustrates the process of data cleaning and refinement for preparing data for generative AI models. It shows the transformation from raw, noisy data with errors and inconsistencies to refined, clean data, ultimately leading to higher quality AI results with better accuracy and less bias.
The Rise of Generative AI
While traditional AI often focuses on classification or prediction, Generative AI represents a paradigm shift by creating new content. Tools like ChatGPT, a text-based conversational agent, and Midjourney, an AI-driven image generator, demonstrate the immense creative potential of these systems.
However, the "generative" nature of these tools introduces unique risks. Because these models are trained on massive datasets of human-created content, they can mirror the flaws found in that data. This leads to several critical issues:
Hallucinations: The tendency of models like ChatGPT to generate information that sounds plausible but is factually incorrect.
Misinformation: The accidental or intentional spread of false information through generated content.
Bias: When statistical probabilities within the training data lead the AI to reproduce harmful stereotypes.
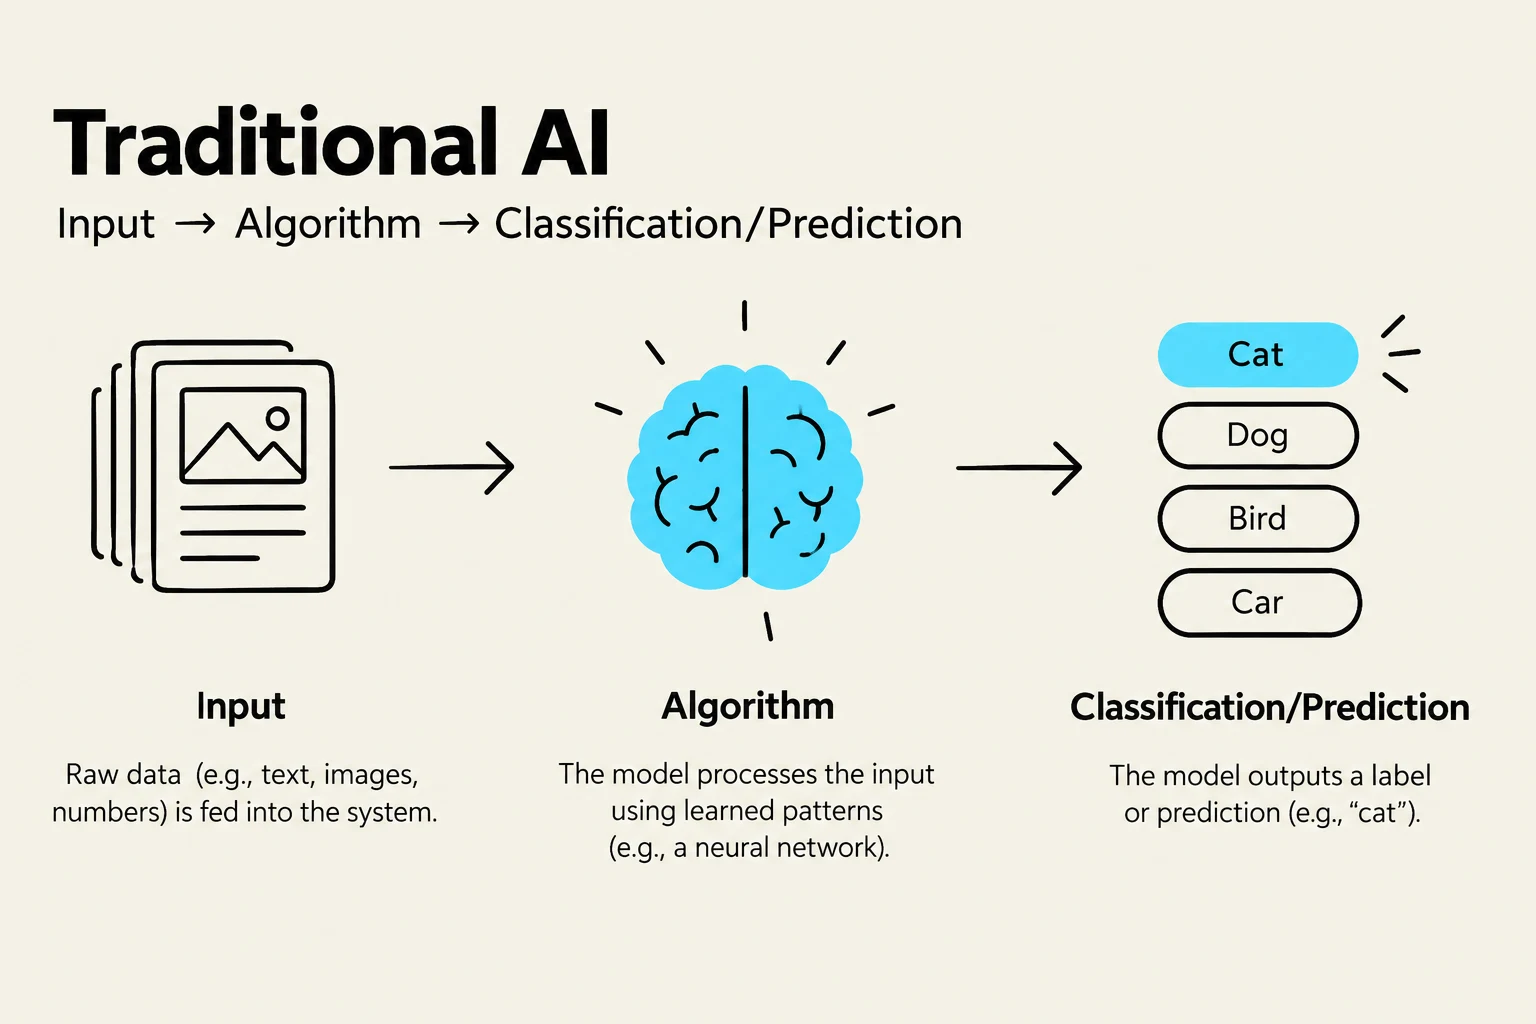
This diagram illustrates the basic process of traditional Artificial Intelligence, showing how input data is processed by an algorithm to produce a classification or prediction.
A Sociotechnical Perspective
To truly understand AI, we must move beyond seeing it as just a piece of software. Instead, we should view AI through a sociotechnical perspective. A sociotechnical system is composed of interrelated elements—technology, humans, and institutions—working toward shared goals.
Using Latour’s Actor–Network Theory (ANT), we can see that "The AI" is never just the model itself. It is a vast network of actors, including:
Non-human actors: Computing infrastructure, model architectures, and the data itself.
Human actors: Developers, users, and the creators of the original training data.
Institutional actors: The rules, laws, and ethical guidelines that shape how the technology is used.
In this view, an outcome (like a biased response or a copyright dispute) is not just a "glitch" in the code; it is a result of the entire network.
Ethics, Ownership, and Responsibility
The integration of AI into society raises profound ethical questions that developers and users must navigate.
Copyright and Ownership
As tools like Midjourney become more prevalent, the question of "who owns the art" becomes central. If an AI generates an image based on millions of human-created works, is the output original? Who holds the copyright: the user who wrote the prompt, the developer of the model, or the original artists whose work trained the system?.
The Burden of Responsibility
A common misconception is that AI automates decision-making to the point where humans are no longer needed. On the contrary, Generative AI does not remove human responsibility.
Instead, AI redistributes responsibility across the sociotechnical network. When an AI produces harmful content, we should not simply ask, "What did the AI do?" We must ask, "What network of human, institutional, and technological actors produced this outcome?". Developers make critical choices about what content is considered offensive, how the system responds to uncertainty, and how to manage privacy and safety.
Key Takeaway: In the age of AI, responsibility is not eliminated; it is distributed. Understanding the "network" is essential for effective governance and ethical deployment.
Keep reading for free.
Create an account to finish this reading and make it part of your study routine.