Learn how to use regression equations for predicting unknown values through estimation, calculate the standard error of the estimate, and perform cross-validation to ensure model reliability.
In statistical modeling, creating a regression equation is only the first step. While a multiple regression model allows us to use several independent variables (predictors) to explain a single dependent variable, the true utility of the model lies in its ability to predict unknown values. This process, known as estimation, requires us to understand not just the predicted value itself, but the degree of error inherent in that prediction. To ensure a model is truly useful, researchers must move beyond the initial sample and perform rigorous validation to see how the equation performs on new data.
Estimation from the Regression Equation
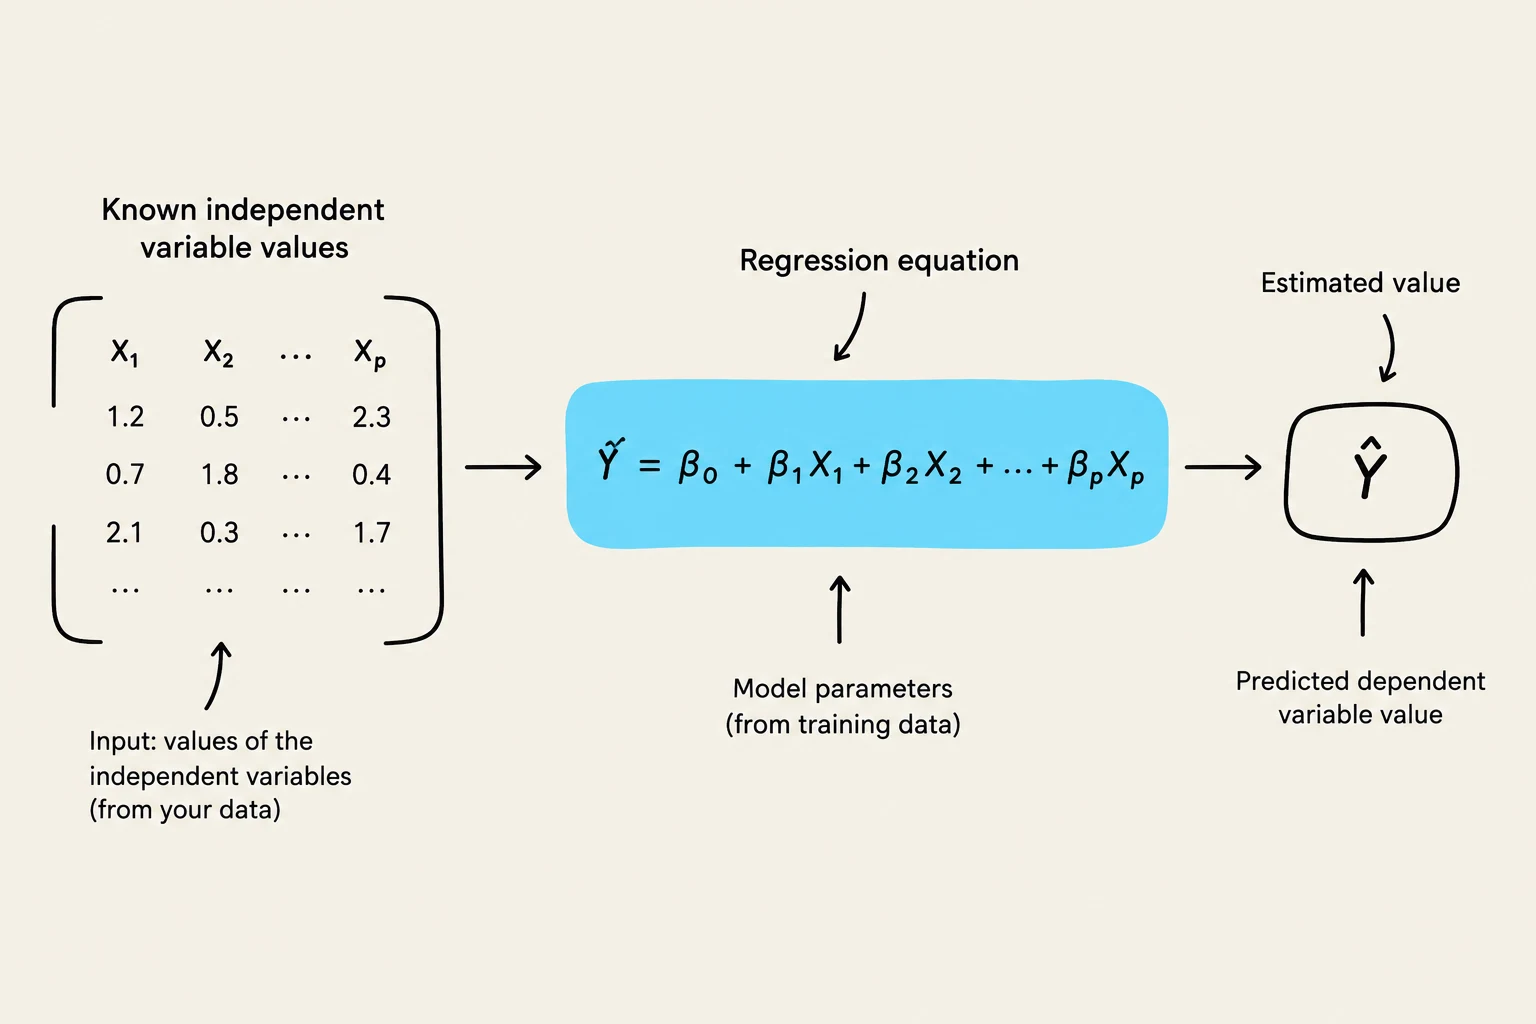
Estimation is the process of using a previously developed regression equation to predict an unknown value for a specific individual. When we have a multiple regression equation, it takes the form of several slope coefficients multiplied by their respective independent variables, plus a constant.
For example, consider a model predicting Physical Activity (PA) based on Self-Efficacy (SE):
YPA=0.52⋅XSE−3.08
If an individual reports a Self-Efficacy score of 25, we can estimate their PA as follows:
YPAYPAYPA=0.52(25)−3.08=13−3.08=9.92
The stronger the correlation between the predictors and the outcome, the more accurate these estimations will be.
This diagram illustrates the process of linear regression, where input values of independent variables are used with model parameters to calculate a predicted dependent variable value through a regression equation.
Quantifying Error: The Standard Error of the Estimate
No prediction is perfect. The difference between an actual observed score (Y) and the score predicted by our equation (YP) is known as a residual. Because these residuals exist, we need a way to measure the "average" error of our model.
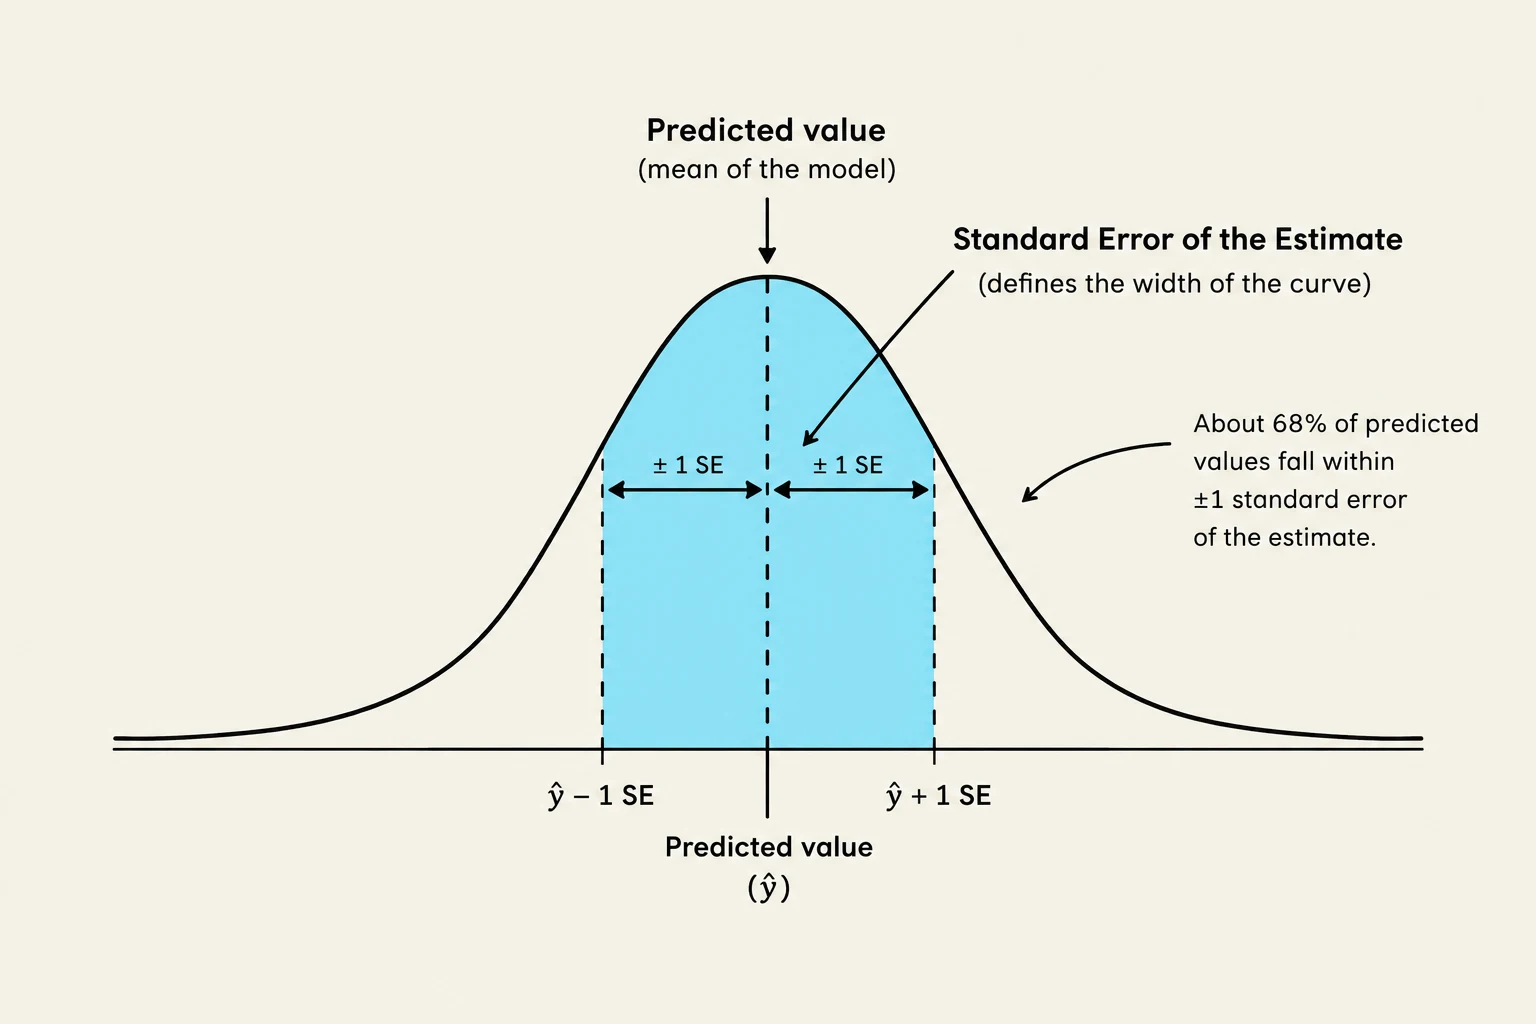
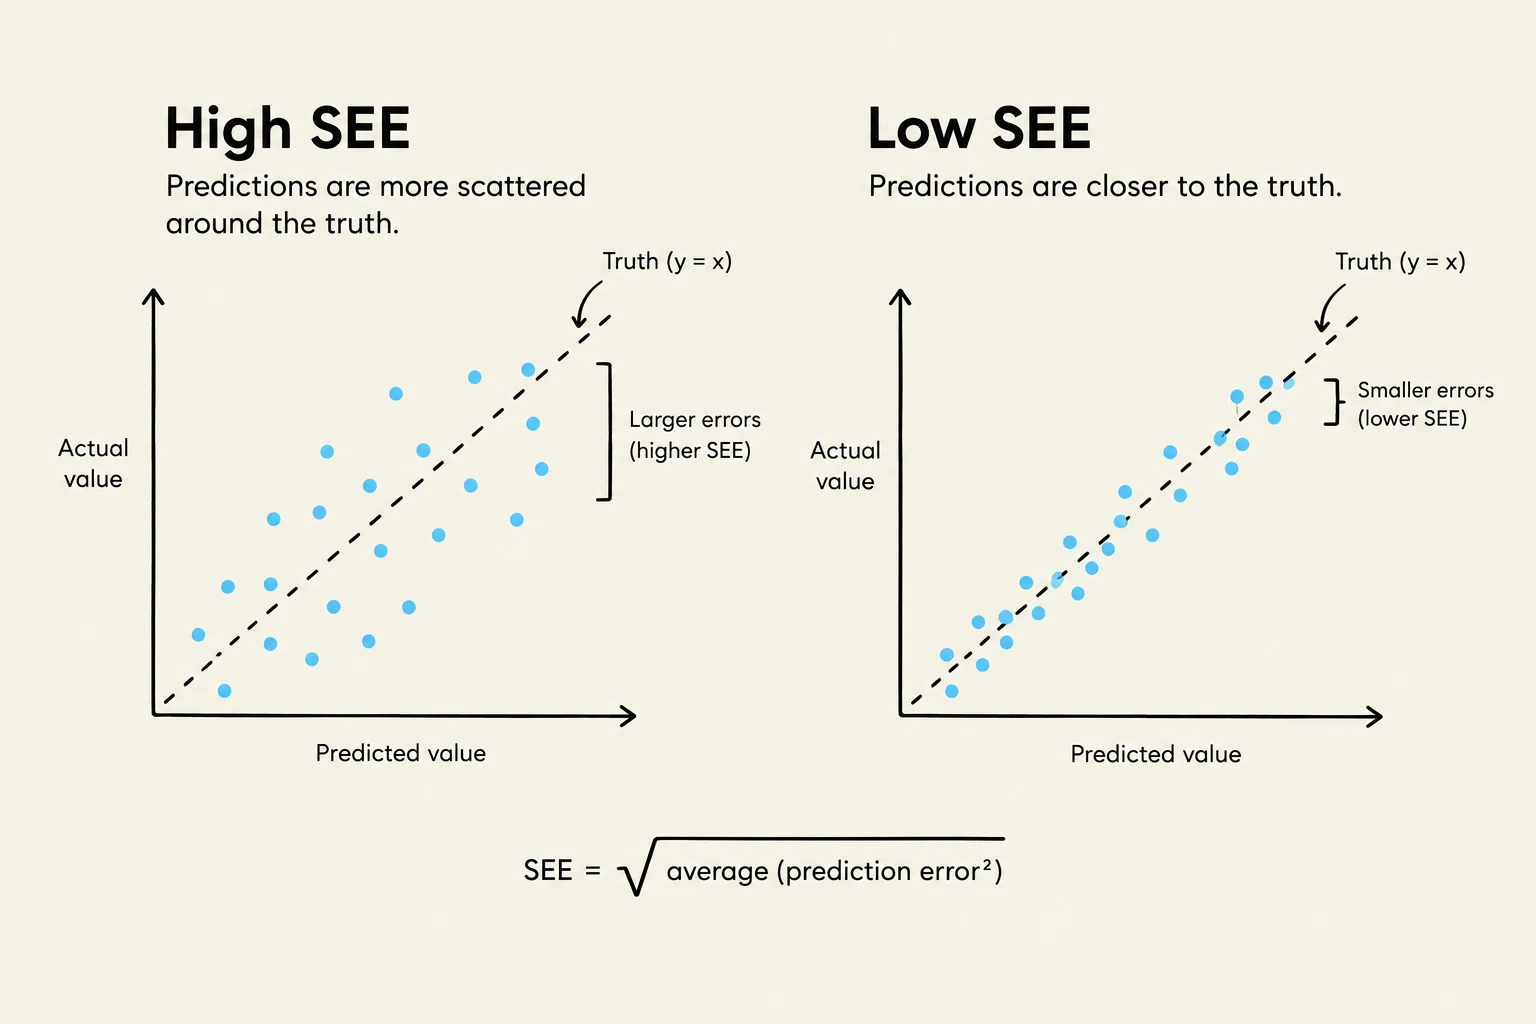
The Standard Deviation of the Residuals represents the spread of these errors. However, the most common metric used in regression is the Standard Error of the Estimate (SEE). The SEE provides a measure of the accuracy of predictions; a smaller SEE indicates that the data points are clustered closely around the regression line, suggesting a more precise model.
One way to calculate the SEE is by using the standard deviation of the dependent variable (σy) and the multiple correlation coefficient (r):
SEE=σy1−r2
Exam Tip: When comparing two different regression equations, the one with the lower SEE is generally considered the better equation for accurate prediction.
Confidence Intervals Around an Estimate
Because the SEE tells us how much our predictions might vary, we can use it to create a Confidence Interval (CI). A confidence interval provides a range of values within which we are reasonably certain the true value will fall.
Commonly, researchers use a 95% or 99% confidence level. To calculate this, we multiply the SEE by a constant (Z-score) based on the desired level of confidence:
For a 95% CI, use 1.96⋅SEE
For a 99% CI, use 2.58⋅SEE
Worked Example:
If our predicted value (YP) is 9.9 and our SEE is 6.3, the 95% Confidence Interval would be:
This means we are 95% confident the actual value lies between -2.4 and 22.2.
A normal distribution curve illustrating the concept of standard error of the estimate, showing that approximately 68% of predicted values fall within one standard error of the mean.
Validation: Cross Validation, Constant Error, and Total Error
A common pitfall in statistics is "overfitting," where a model works perfectly for the group of people used to create it but fails miserably when applied to anyone else. To prevent this, we use Cross Validation.
In cross validation, you develop the equation using one half of your sample and then test its predictive power on the remaining half of the sample. During this validation phase, we look at two specific types of error:
Constant Error (CE)
Constant Error measures whether the model systematically overestimates or underestimates the actual values. It is calculated as the difference between the mean of the actual values (Yˉ) and the mean of the predicted values (YˉP):
CE=Yˉ−YˉP
To determine if this error is statistically significant, a dependent samples t-test is performed between the actual and predicted means.
Total Error (TE)
While CE looks at systematic bias, Total Error represents the combination of both the systematic error (CE) and the random error (SEE). It is calculated using the sum of the squared differences between actual and predicted values:
TE=N∑(Y−YP)2
Many experts recommend Total Error as the single best evaluator of regression equations during the cross-validation process.
This illustration compares high and low Standard Error of the Estimate (SEE) in predictions. High SEE indicates predictions are more scattered around the truth, while low SEE means predictions are closer to the truth. The formula for SEE is also provided.
By understanding estimation, quantifying error through the SEE, and validating the model through cross-validation, researchers can ensure their regression models are not just mathematical curiosities, but reliable tools for real-world prediction.
Keep reading for free.
Create an account to finish this reading and make it part of your study routine.