


In the field of epidemiology, researchers aim to quantify health outcomes to understand how diseases behave within populations. These outcomes can be expressed in different mathematical ways depending on the nature of the data. Most commonly, outcomes are categorized as discrete variables, such as the presence or absence of a specific disease, or continuous variables, such as blood pressure or glucose levels. While continuous variables are often analyzed using linear regression, much of epidemiological research focuses on categorical dichotomous outcomes—where an individual either has the condition or does not.
To measure the frequency of these dichotomous outcomes, epidemiologists use the ratio of the number of individuals with the outcome (the numerator) to the number of individuals at risk (the denominator). This results in two primary absolute measures: incidence and prevalence.
Prevalence: Measuring Existing Events
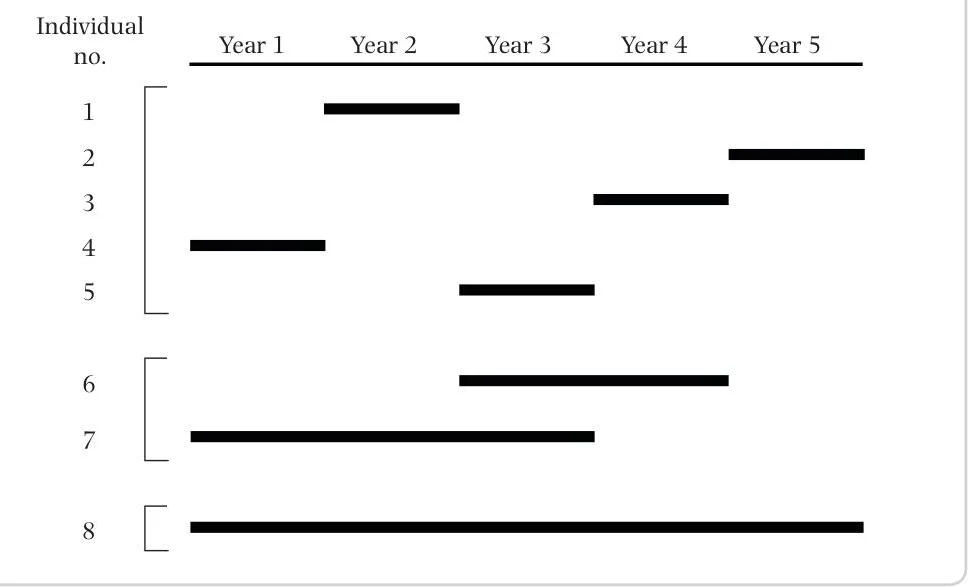
Prevalence refers to the frequency of an existing outcome within a population. Unlike incidence, which focuses on the "flow" of new cases, prevalence provides a "snapshot" of the total burden of a disease at a given time.
Prevalence is categorized into three distinct types:
- Point prevalence: The proportion of individuals who have the outcome at a specific, single point in time.
- Period prevalence: The proportion of individuals who have the outcome during a defined time interval (e.g., one year).
- Cumulative (lifetime) prevalence: The proportion of people who have experienced the event at any time in the past up to the present.
A critical relationship exists between prevalence, incidence, and the duration of a disease. In a stable population (where incidence and prevalence are relatively constant), the relationship can be expressed as:
Keep reading for free.
Create an account to finish this reading and make it part of your study routine.
Continue reading freeAlready have an account? Log in
Updated