Introduction to Probability and Discrete Distributions
Explore the fundamental rules of probability, including experiments, outcomes, events, and calculations like the complement rule, addition rules, joint, and conditional probabilities. Learn about discrete variables and valid probability distributions, with a focus on expected value and standard deviation as measures of
Probability is the mathematical language used to quantify uncertainty. Whether you are analyzing shipment delays, customer payment methods, or financial risks, understanding how to calculate the likelihood of specific occurrences is fundamental to data-driven decision-making. This article explores the foundational rules of probability and how they apply to discrete variables and expected outcomes.
The Building Blocks: Experiments, Outcomes, and Events
To study probability, we must first define what we are measuring. An experiment is any process that results in an uncertain outcome, such as recording the status of a delivery package. An outcome is a single possible result of that experiment, such as a package being "Delayed". An event is a collection of one or more outcomes that satisfy a specific condition. For example, if we are interested in all non-ideal deliveries, the event "Delivery Issues" might include the outcomes "Delayed," "Damaged," and "Lost".
This diagram illustrates the concept of probability by showing the experiment of rolling a die, its possible outcomes (1 through 6), and a specific event (rolling an even number).
Mutually Exclusive Outcomes
Two outcomes are considered mutually exclusive if they cannot happen at the same time. For instance, if a customer is classified by using exactly one payment method, the outcomes "Cash" and "Credit Card" are mutually exclusive.
Rules of Probability Calculation
Once we define our events, we use specific rules to calculate their likelihoods.
The Complement Rule
The complement of an event is the event not occurring. Because the sum of the probability of an event and its complement must equal 1, we use the formula:
P(not A)=1−P(A)
If 76% of employees complete training, the probability of the complement (not completing training) is 1−0.76=0.24.
Addition Rules: Mutually Exclusive vs. Overlap
When we want to find the probability of one event or another occurring, we use the Addition Rule.
Mutually Exclusive Events: If the events cannot overlap, simply add their probabilities.
P(A or B)=P(A)+P(B)Example: If P(Mobile)=0.42 and P(Desktop)=0.33, then P(Mobile or Desktop)=0.75.
Events with Overlap: If the events can happen simultaneously, adding them directly would count the overlap twice. We must subtract the joint probability once:
P(A or B)=P(A)+P(B)−P(A and B)
Joint and Conditional Probability
Understanding the relationship between two variables requires distinguishing between joint and conditional probabilities.
Joint Probability: This is the probability that two events happen at the same time, often represented as P(A and B). In a table of 300 shipments, if 12 were both "Air" and "Damaged," the joint probability is 30012=0.04.
Conditional Probability: This is the probability of an event occurring given that another event has already occurred. The wording "among [group]" often signals a conditional probability.
P(A∣B)=P(B)P(A and B)
If we want to know the probability a package is damaged given it was sent via Air, we use the total number of Air shipments as our denominator.
Reverse Conditional Probability: This involves switching the condition. For example, instead of P(Damaged∣Air), we might ask for P(Air∣Damaged). Here, the denominator becomes the total number of damaged packages.
This table illustrates the relationship between shipping method (Air or Ground) and item condition (Damaged or Not Damaged), including totals and grand totals.
Exam Tip: The Independence Check
To check if two events are independent, compare the conditional probability to the marginal probability. If P(A∣B)=P(A), the events are independent. If they are not equal, the events are dependent.
Discrete Probability Distributions
A discrete variable is one that has separate, countable values, such as the number of customer returns. This is distinct from continuous variables, such as weight or temperature, which can take any value within a range.
Valid Distributions
For a discrete probability distribution to be valid, it must meet two criteria:
Every individual probability P(x) must be between 0 and 1.
The sum of all probabilities must equal exactly 1.
Expected Value (The Long-Run Average)
The Expected Value, denoted as E(X), is a probability-weighted mean. It represents the long-run average value we would expect if we repeated the experiment many times. To calculate it, multiply each possible value x by its corresponding probability P(x) and sum the results:
E(X)=∑x⋅P(x)
If a distribution has values $x = {0, 1, 2, 3}$ with probabilities ${0.15, 0.35, 0.30, 0.20}$, the calculation is:
E(X)=(0⋅0.15)+(1⋅0.35)+(2⋅0.30)+(3⋅0.20)=1.55
.
Standard Deviation and Risk
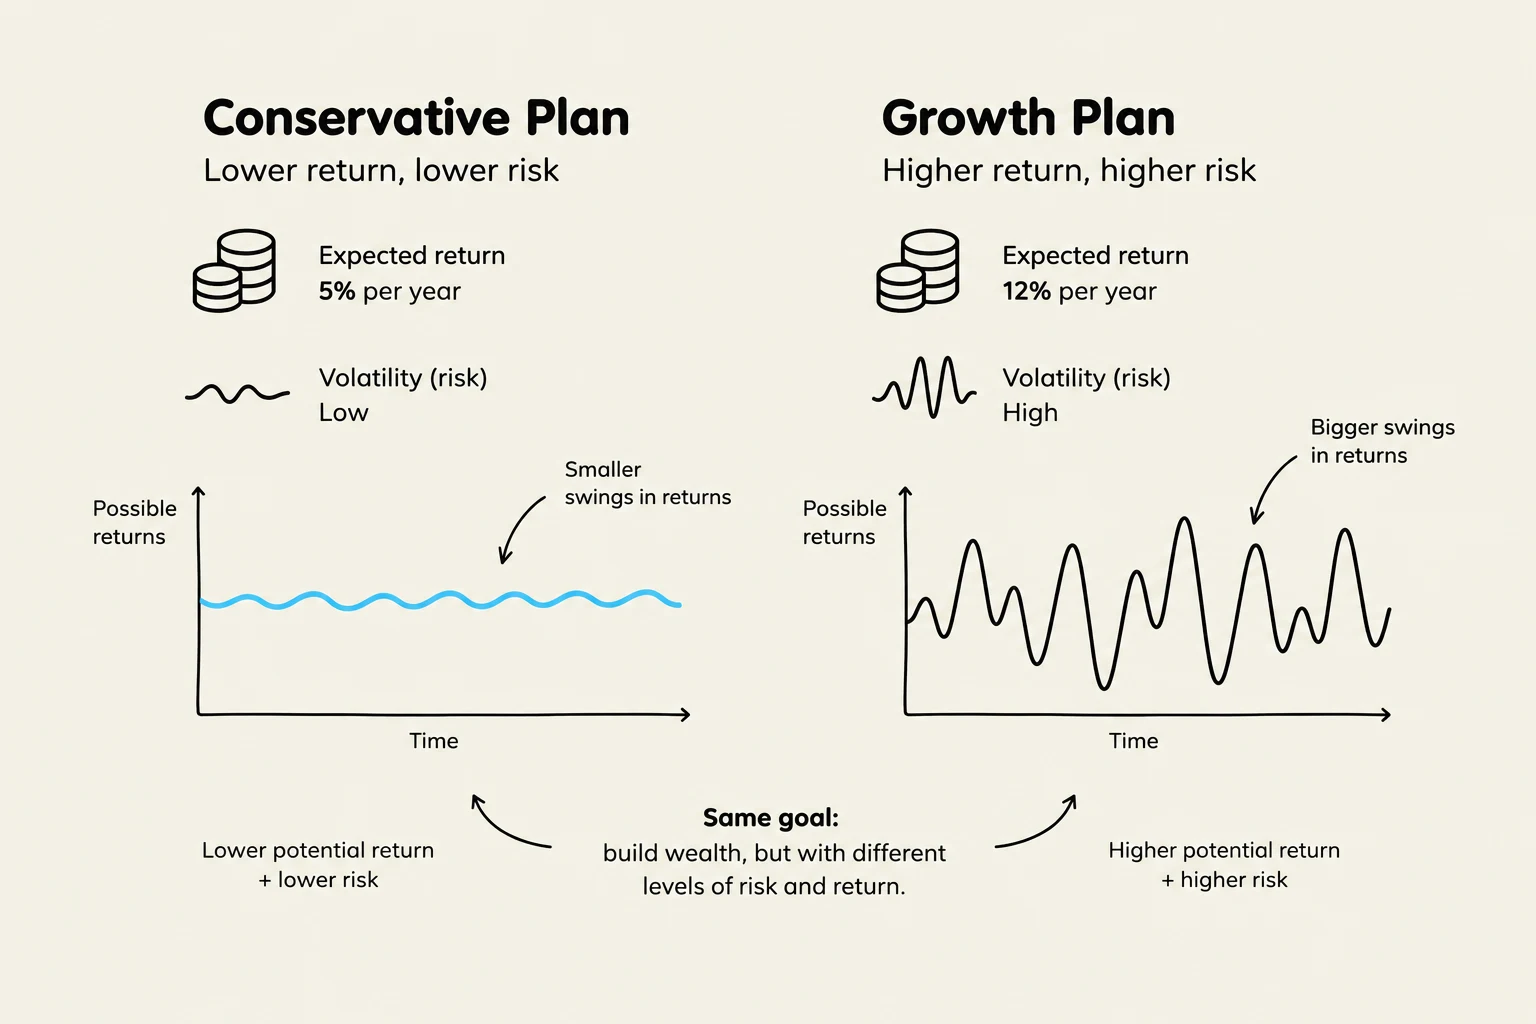
While the expected value tells us the average, the standard deviation tells us how much the actual outcomes vary or "spread" around that average. It is expressed in the same units as the original variable.
In business contexts, standard deviation is a proxy for risk.
Plan
Expected Profit
Standard Deviation
Plan A
$30,000
$8,000
Plan B
$36,000
$27,000
In the table above, Plan B has a higher expected profit, but its much larger standard deviation indicates significantly higher uncertainty and risk compared to Plan A.
This illustration compares a conservative investment plan with a growth investment plan, highlighting their respective expected returns, volatility (risk), and the nature of their potential returns over time.
Keep reading for free.
Create an account to finish this reading and make it part of your study routine.